It stops making things up
Without TeamGraph, a quarter of the answers about the team's own code were invented. With TeamGraph, none — the verify gate returns a MISS instead of a confident guess.
On questions about a team's own codebase, Claude Code was measured with and without TeamGraph. The memory made the agent faster, cheaper, and markedly more likely to be right — and it stopped inventing answers.
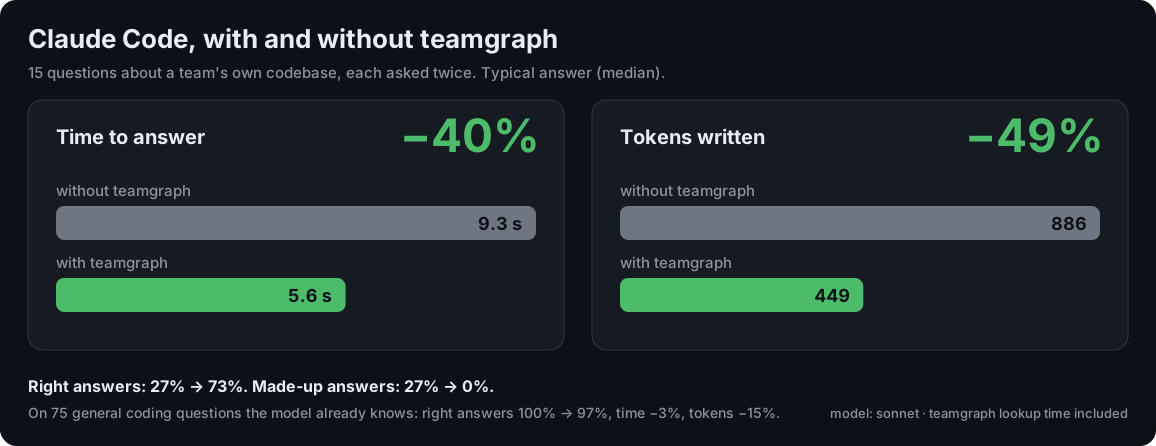
Questions about a team's own codebase, answered by Claude Code with and without TeamGraph.
Without TeamGraph, a quarter of the answers about the team's own code were invented. With TeamGraph, none — the verify gate returns a MISS instead of a confident guess.
On 30 questions no note answers, TeamGraph sometimes offered the wrong note — and the agent set it aside every time. Bad recall costs nothing; it just isn't used.
TeamGraph finds the right note for 88% of questions. The misses are usually a question about the same technology as another note — the next thing being worked on.
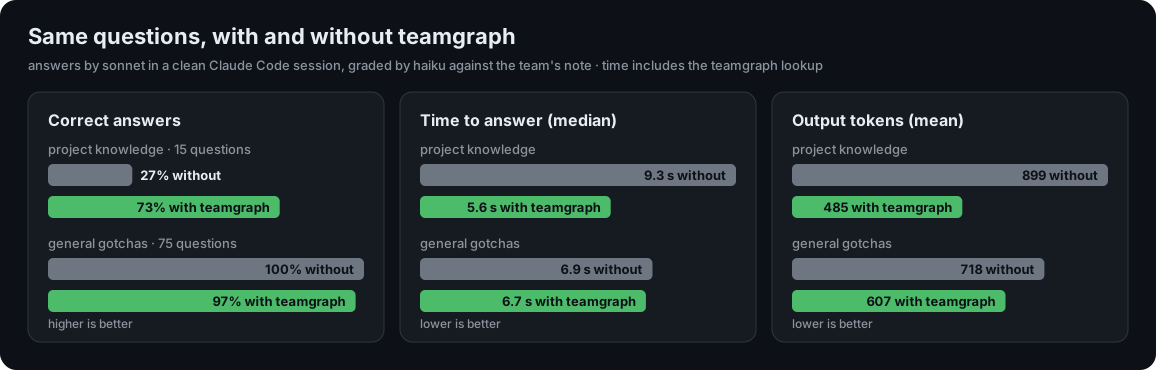
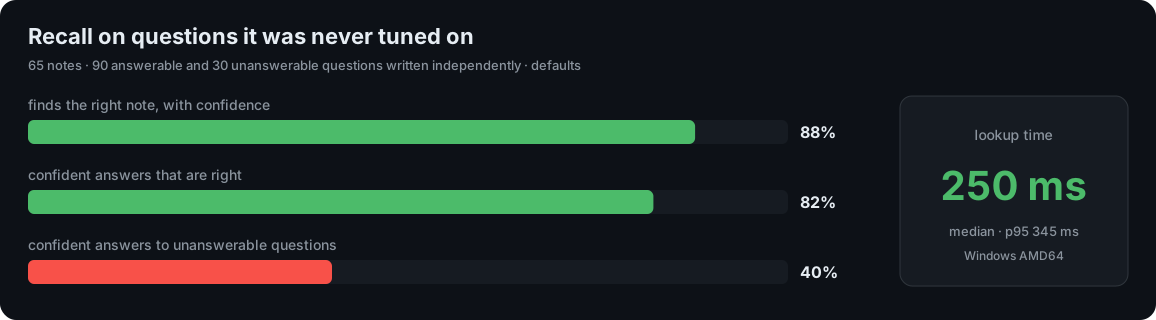
bench/ directory.Install TeamGraph, point it at your project, and see the difference on the questions your team actually asks.